 CodeRabbit
Automated Coding Planner.
Faster discovery, by pulling the right context into the prompt from the tools a team already uses.
I led design end to end: the key workflows and journeys, and built the case for the two surfaces that shaped the product.
Rulesets decide which issues get a plan. A plans list gives people one place to find them, instead of treating Linear or Jira as the way in.
Garbage in
A ticket is one line. The context lives in nine other tools.
Customer complaints, Slack threads, last quarter’s failed attempt: none of it makes it into the prompt.
Garbage out
A better-worded prompt still gets you a generic plan.
Prompt engineering articulates the requirements but doesn’t fill in the specifics. The intent is usually there, but the plan scaffold generally lacks the nuance of context:
- How many colors, and where?
- What’s already broken?
- What did the team decide?
- What are customers complaining about?
What the agent needs
The same prompt, with the gaps filled in from the team’s own tools.
The agent pulls context from the connected sources, so the prompt now carries nuances that would otherwise have been missed. Every source is documented and cited, so the engineering team can verify it.
Context
Code got faster. It also got worse.
Teams ship more code with AI, and trust it less. The less context a prompt carries, the wider the gap between the code it generates and a PR that merges.
CodeRabbit reviews code after it’s written. Planning gets it in before the code exists.
Delivery stability for every 25% rise in AI adoption
Google DORA, State of DevOps 2024More issues in AI-authored pull requests
CodeRabbit, AI vs human code report, 2025Of developers say AI answers are almost right, but not quite
Stack Overflow Developer Survey 2025Problem
Much of the wasted work starts with a poorly defined task.
Before an engineer can write a good prompt, they have to go and find the context. That’s where the time goes:
- Gathering context by hand is slow, so discovery drags.
- Prompts with loose guardrails create rework later, in rebuilds, scaling fixes and review.
- Knowledge that lives in niche tools, or needs a specialist to read, gets missed.
- An engineering lead still has to review and approve the plan before work starts.
Planning competes with shipping
Writing a real plan takes time away from delivery, so most issues get a Slack thread and a guess. The first draft had to be free and instant, so people edit a plan instead of writing one.
An AI plan only counts if people believe it
A plan that hides its reasoning, guesses the wrong repo or arrives as a wall of text gets thrown away. People need to see what it assumed, and be able to change it.
A plan that never reaches the editor is wasted
Planning only pays off if the plan can be built from, and the resulting PR links back to the issue it came from.
Research and personas
One shared job across three roles.
We spoke with more than two dozen ICs about their planning rituals, along with their EMs and PM partners, to understand how work gets planned and where codegen and prompting fall short.
All three roles had to execute the same job, but from different angles.
Spends the first hour of a ticket working out what it actually means. Wants clear steps and file pointers to hand to an editor or agent.
“Honestly, the first hour is just figuring out what the ticket wants.”Senior engineer, Series B fintech
Scopes epics from memory, and they still get under-scoped. Wants a plan she can edit and assign.
“Every sprint I’m re-scoping epics from memory, and trying to remember whether another team has turned up something new.”Engineering manager, developer tools
Loses track of an issue once engineering picks it up. Wants the PRs linked back to it.
“I don’t know it shipped until someone tells me.”Product manager, B2B SaaS
What I tried
What I tried before the plan.
Each direction had its trade-offs. What stood out across all of them was trust, and how to communicate it to people with very different skill sets.
Prompt templates
Puts the work back on each person.
The agent’s own plan mode
Only the agent can see it. The team can’t review it.
Issue straight to PR
Skips the cheapest moment to catch a bad assumption.
A detailed spec
Goes stale as soon as the code moves.
An editable, versioned plan
Shipped. One shared plan, before any code, with the assumptions in the open.
Strategy
A new product line.
Code review comes after the work is done. Planning lets CodeRabbit help before any code is written.
That means a new product sold into accounts we already had, a record of plans and issue-to-PR history that’s hard to walk away from, and a buyer beyond reviewers: the EMs and PMs who plan the work.
The bets
- Trust before automation
- Close the loop from plan to PR before adding features
- Make editing cheaper than re-prompting
- Treat picking the right repo as a trust guardrail
The unknowns
- Will EMs and PMs plan this way every sprint, or try it once?
- Can repo prediction stay accurate without asking too often?
- Does plan-to-PR conversion hold on hard, multi-phase epics?
- Should a stale plan replan itself, or just prompt?
Ticket to PR
From a thin ticket to a reviewed plan.
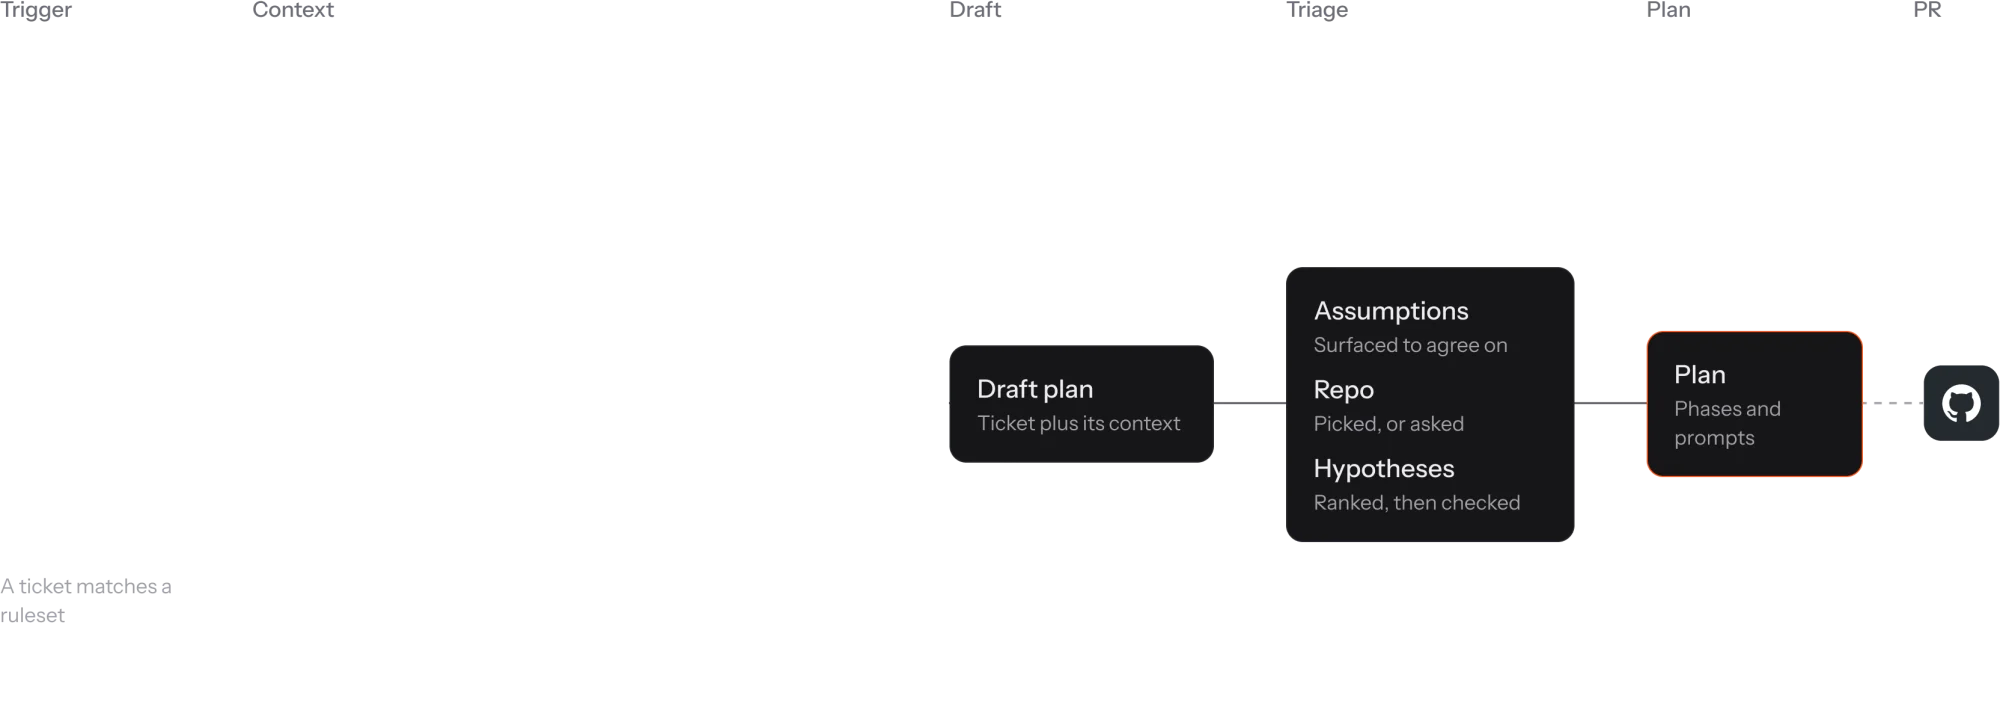
The trigger is a ticket that matches a ruleset. The plan is built from everything around it, triaged before anyone reads it, and handed to an agent. The PR links back to the plan.
 JiraTrigger: a ticket that matches a ruleset
 LinearTrigger: a ticket that matches a ruleset
 Slack#web-app · #design-system threads
 GitHubweb-app repo, token usage, code owners
 NotionPRDs and the theming RFC
 ConfluenceDesign token audit
 FigmaTokens file and the design system library
 Google DocsKickoff and review notes
 GmailCustomer threads asking for dark mode
 ZendeskTickets labeled UX issues
 IntercomConversations tagged accessibility
 GongSales calls where theming came up
 Research notesInterview notes on night-time use
 SalesforceDeals waiting on accessibility fixes
 HubSpotFeature requests from trial accounts
 Product analyticsTheme toggle usage
 SentryErrors in staging, like BUG-771
 DatadogIncidents and performance limits
Decisions
Five key decisions.
The system could already generate plans and even run them. The main decisions were about trust: when the AI drafts, how it shows uncertainty, and who makes the final call.
The plan
A plan you can question, annotate and hand off.
Every plan has the same schema, so people learn to read it once. It runs top-down: what was asked, what the plan assumed, the phases of work, and where each fact came from.
Assumptions sit above the phases because that’s where we want people to focus and push back. Catching a gap in an assumption is what the human in the loop is there for. The sources sit at the end, like a bibliography.
- Title
- Description
- Priority and a link back to the ticket
Keeps the plan checkable against what was asked.
- The assumption, stated plainly
- The direction chosen, against its alternatives
- The reasoning behind it
Placed before the work, because a wobbly assumption is where a plan goes wrong.
- PhaseA modular unit, executed independently of the other phases
- TaskExecuted in order within its phase, with file pointers
Phases can run in any order. Tasks inside a phase can’t.
- Docs
- Linked issues
- Customer calls
- Bug reports
Every source the plan drew on, cited like a bibliography, so a reviewer can check a claim.
Replanning
Annotate, discuss, then replan once.
There are three ways to work with a plan. Chat freely with the agent. Tag a section, like Task 2, so it drops into the composer and the agent knows exactly what you mean. Or highlight a granular section to make a very focused remark.
Each one queues a change. When you’re ready, one replan applies them together and saves a new version.
The theme resets when people switch devices. Should it live somewhere other than localStorage?
Handoff
One plan, two readers.
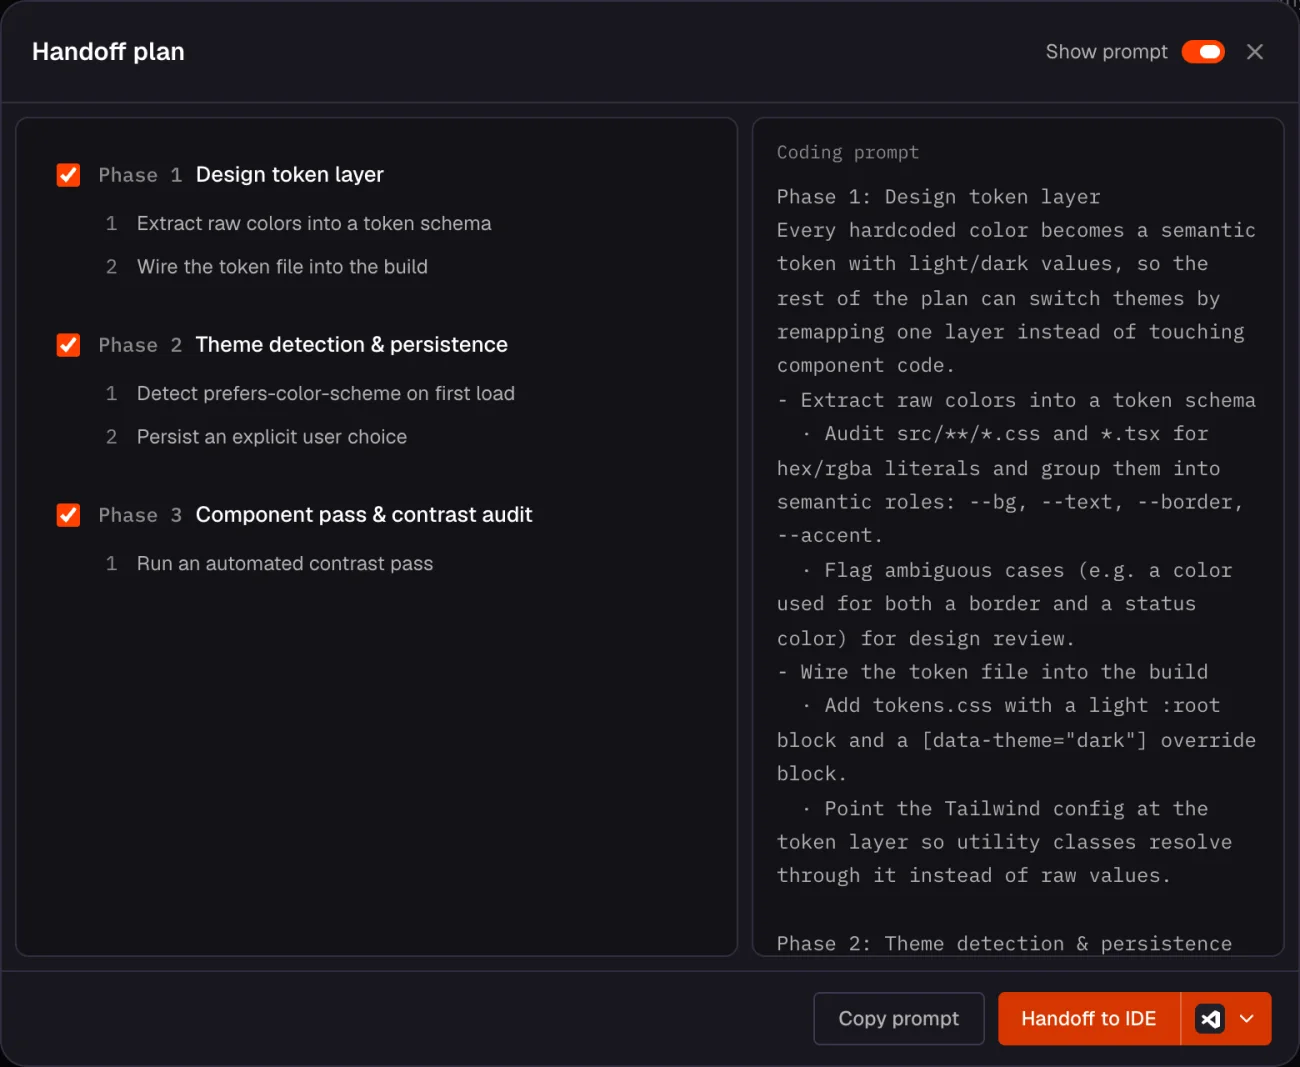
The handoff packages the plan two ways: a checklist of phases and tasks for the engineer, and the same plan as a coding prompt for an agent. When the PR opens, it links back to the issue.
Automations
Automating plan creation.
Creating plans by hand defeats the purpose. But generating one for every new issue would be expensive, since each plan means scanning and indexing a lot of context, and most of those plans would go unused. Instead, teams set rules that filter for the non-trivial issues worth planning, and only an issue tracker can trigger one. Teams decide which issues get a plan while still being able to automate the entire process.
Edge cases
When things aren’t straightforward.
The states that decide whether people keep trusting the plan, from a missing repo to a source that’s been switched off.
Not sure of the repo
Below the confidence threshold, CodeRabbit asks in the ticket’s comments. A user replies, and plan generation resumes.
An unsure assumption
The plan doesn’t score itself. Each assumption is stated plainly, with alternatives to switch to.
A stale plan
If enough of the upstream content changes, the planner detects that a refactor is needed and prompts the user to create a new plan, bumping the version.
An older version
Only the latest version is editable, but you can revert to any earlier version and keep editing from there.
A rule that’s too narrow
The ruleset preview shows what it would have caught last month, and warns before you save.
A paused source
A source can be switched off without disconnecting it, so teams can test which sources are worth it and which only add noise to their plans.
Playground
The whole loop, live.
1/1
-
-
Metrics
The north star metric.
We measured plans that became a merged PR, linked back to the issue. Plans generated and plans viewed are easy to inflate. A merged PR is the number that indicates adoption, because it only happens when a plan was good enough to build from.
The funnel, indexed to 100 plans
Guardrails
Outcome
Shipped to GA.
The planner shipped to every CodeRabbit customer. In the month after launch, monthly plan creators grew by about 70%, and weekly creators peaked near 80% before settling around 60% (Fig. 1).
A plan counts when it’s handed off. Plans worked four or more times were handed off nearly four times as often as plans left untouched (Fig. 2). Plans started in the app were also handed off more often than ticket-triggered ones.
Fig. 1 Plan creators, indexed to day 1
Fig. 2 Handoff rate by rounds of editing, relative to one version
Notional: indexed and relative values only. Absolute numbers are confidential.
Reflections
What it cost, and what I learned.
Tradeoffs
Plan detail
Too much goes stale, too little hides assumptions.
Planning has to pay for itself
It’s a step before the fun part, so it has to save more time than it takes.
Assumptions take attention
Too many, and people skim.
Learnings
Design for trust
In AI products, the higher the risk to the outcome, the more clearly the assumptions and confidence need to be communicated.
Compile edits, then replan
A robust plan takes real context, time and compute to generate, so one holistic replan beats piecemeal fixes.
Plans need to result in code
The handoff to a PR, linked back to the issue, is what shows a plan actually got used.
What I’d redo
Instrument trust from day one
We tracked plans and handoffs from launch, but not how often people switched an assumption to an alternative. That’s the clearest sign the flags were working, and we added it late.
Meet developers where they work
Plans lived in CodeRabbit, so developers made a round trip from their coding tool and back. I’d bring the plan into the IDE and the tracker they already use.
Fit each team’s planning ritual
Adoption depended on how each organization plans, from sprint ceremonies to ad hoc tickets. I’d design for those rituals earlier instead of assuming one way of planning.
Test on hard epics sooner
Early testing leaned on small, single-repo issues. Multi-repo epics exposed sequencing gaps late.